


 Ruby
 Golang
 .Net
 MCP
 C++
Google Search results are constantly changing. You might find your business ranked first on a good day and slip to fourth place or lower the next.
There can be many reasons for it: a new competitor enters the market, an old one exits, or Google adds new sections to its results page. A search that used to primarily return organic_results can suddenly return a mix of features - top stories, AI Overview, etc.
What are we building?
In this tutorial, we'll build a simple SERP tracker that collects Google Search results, saves historical snapshots, compares them, and generates a report of the changes.
By the end of this tutorial, our system will be able to answer questions such as:
- Which competitors moved up or down?
- Did Google introduce a new SERP feature?
- Did a previously visible feature disappear?
At a high level, the workflow looks like this:
Keywords → SerpApi → Google Search results → Store snapshot → Compare with previous snapshot → Identify changes
Why SerpApi?
The tracker needs current Google Search data, and an LLM alone isn't a reliable source for the state of a SERP. We need a search layer that can retrieve the results we want to monitor. SerpApi's Google Search API returns structured Google results, including organic results and various SERP features.
Getting started with SerpApi
Setting up your account
First, you need a SerpApi account to start scraping Google Search. SerpApi's Free Plan provides 250 searches per month, which you can use to retrieve the data you need.
Step 1: Sign up for an account or sign in to SerpApi if you already have one.
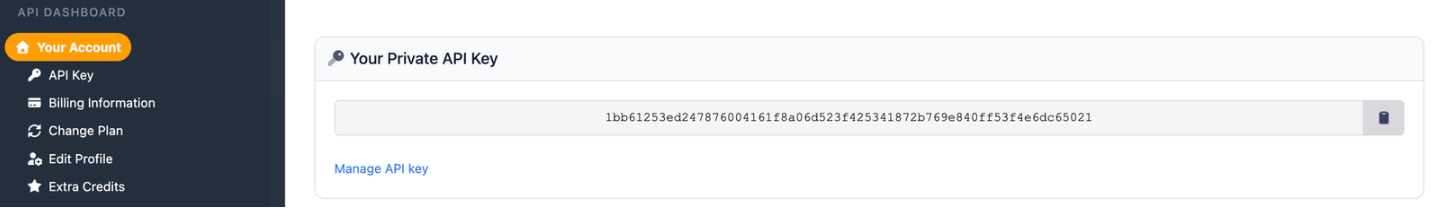
Step 2: Get your API key from your dashboard.
Installing the required libraries
SerpApi has its own integrations for different languages and tools. You can also send GET requests directly or use SerpApi's libraries.
We'll be creating this tracker using SerpApi's Python Library. You can install SerpApi's Python library and other relevant libraries.
pip3 install serpapi
pip3 install python-dotenv
Reviewing the Google Search API documentation
SerpApi has detailed, well-explained documentation for the Google Search API. You can explore the API and see which details it returns when you make a request. You can also run a few requests on our Playground to see how it works.
 SerpApi
Let's start scraping
First, we'll decide the keywords we would like to monitor.
keywords = ["project management software", "best project management software", "project management tools", "asana alternatives"]
Next, let's import our libraries in the script and prepare our client to send requests.
import serpapi
import os
from dotenv import load_dotenv

load_dotenv() # This is for loading your SERPAPI_API_KEY from the .env file.
client = serpapi.Client(api_key=os.getenv("SERPAPI_API_KEY"))
Now that we have our client ready, we can loop over our keywords to get their respective SERPs, store them in a normalized form and also make note of presence of other features. We'll also use location-specific parameters to make the results more relevant, as Google search results can vary depending on the user's location.
today = {}

for keyword in keywords:
    response = client.search({
        "engine": "google",
        "q": keyword,
        "location": "Austin, Texas, United States",
        "google_domain": "google.com",
        "hl": "en",
        "gl": "us"
    })

    today[keyword] = {
        "organic_results": [
            {
                "position": item.get("position"),
                "title": item.get("title"),
                "link": item.get("link")
            }
            for item in response.get("organic_results", [])
        ],
        "serp_features": {
            feature: bool(response.get(feature))
            for feature in [
                "ai_overview",
                "answer_box",
                "top_stories",
                "inline_videos",
                "shopping_results",
                "related_questions"
            ]
        }
    }
Here's a snippet of what the normalized JSON today looks like:
{
  "project management software": {
    "organic_results": [
      {
        "position": 1,
        "title": "Best Project Management Software | Monday.com",
        "link": "https://monday.com/"
      },
      {
        "position": 2,
        "title": "Project Management Software | Asana",
        "link": "https://asana.com/"
      },
      {
        "position": 3,
        "title": "Project Management Tool | ClickUp",
        "link": "https://clickup.com/"
      }
    ],
    "serp_features": {
      "ai_overview": true,
      "answer_box": false,
      "top_stories": false,
      "inline_videos": true,
      "shopping_results": false,
      "related_questions": true
    }
  },
  "best project management software": {
    "organic_results": [
      {
        "position": 1,
        "title": "The Best Project Management Software in 2026",
        "link": "https://example.com/best-project-management"
      },
      {
        "position": 2,
        "title": "Best Project Management Tools Compared",
        "link": "https://example.org/project-management-tools"
      }
    ],
    "serp_features": {
      "ai_overview": false,
      "answer_box": true,
      "top_stories": false,
      "inline_videos": false,
      "shopping_results": true,
      "related_questions": true
    }
  }
}
A sample normalized JSON response
today contains all the data you need to save for today's research on the keywords. We can now save this in a separate file to compare when we have new data.
# 2. Save today's normalized results
today_file = f"serp_{date.today()}.json"

with open(today_file, "w", encoding="utf-8") as f:
    json.dump(today, f, indent=2, ensure_ascii=False)
Let's assume we have a snapshot from a previous day. Now, we can use these two data points to run a few comparisons.
yesterday_file = f"serp_{date.today() - timedelta(days=1)}.json"

if os.path.exists(yesterday_file):
    with open(yesterday_file, encoding="utf-8") as f:
        yesterday = json.load(f)

    for keyword in keywords:
        if keyword not in yesterday or keyword not in today:
            continue

        old = {
            item["link"]: item["position"]
            for item in yesterday[keyword]["organic_results"]
        }
        new = {
            item["link"]: item["position"]
            for item in today[keyword]["organic_results"]
        }

        print(f"\nKeyword: {keyword}")

        for link in new.keys() - old.keys():
            print(f"NEW: {link} at position {new[link]}")

        for link in old.keys() - new.keys():
            print(f"DROPPED: {link}, was at position {old[link]}")

        for link in old.keys() & new.keys():
            if old[link] != new[link]:
                print(f"MOVED: {link}, {old[link]} -> {new[link]}")

        old_features = yesterday[keyword]["serp_features"]
        new_features = today[keyword]["serp_features"]

        for feature in new_features:
            if old_features.get(feature) != new_features[feature]:
                print(
                    f"SERP FEATURE CHANGED: {feature}, "
                    f"{old_features.get(feature)} -> {new_features[feature]}"
                )
else:
    print("No yesterday snapshot found. Run the program again tomorrow to compare.")
Here's an example of the comparison output:
Keyword: project management software
NEW: https://www.notion.so/ at position 1
DROPPED: https://www.example.com/, was at position 5
MOVED: https://monday.com/, 1 -> 2
MOVED: https://asana.com/, 2 -> 4
SERP FEATURE CHANGED: ai_overview, False -> True
A sample output for 'project management software' keyword
Note: The data above is fictional and just for an example.
Now, for the last step, we can take this long list of changes and pass them to an LLM to summarize the results and highlight patterns across different keywords.
You can paste in the comparison details obtained from the Python code and add the following prompt.
You are analyzing historical Google Search results
collected using SerpApi.

Summarize the supplied ranking and SERP feature changes.

For each significant change:
- Identify the keyword and affected URL.
- Describe the previous and current positions.
- Summarize any relevant SERP feature changes.
- Identify patterns across keywords when supported by the data.
- Suggest areas for further investigation.

Use only the supplied data for factual claims.
Do not invent reasons for ranking changes.
Clearly distinguish observed facts from hypotheses.
If the data does not establish a cause, say so.

Return a concise report in Markdown.
A sample AI prompt
You can make the prompt more informative by adding more analysis factors. This can make your report more useful for research.
Full code
import serpapi
import os
import json
from datetime import date, timedelta
from dotenv import load_dotenv

load_dotenv() # This is for loading your SERPAPI_API_KEY from the .env file.
client = serpapi.Client(api_key=os.getenv("SERPAPI_API_KEY"))

keywords = ["project management software", "best project management software", "project management tools", "asana alternatives"]

# 1. Fetch and normalize today's results
today = {}

for keyword in keywords:
    response = client.search({
        "engine": "google",
        "q": keyword,
        "location": "Austin, Texas, United States",
        "google_domain": "google.com",
        "hl": "en",
        "gl": "us"
    })

    today[keyword] = {
        "organic_results": [
            {
                "position": item.get("position"),
                "title": item.get("title"),
                "link": item.get("link")
            }
            for item in response.get("organic_results", [])
        ],
        "serp_features": {
            feature: bool(response.get(feature))
            for feature in [
                "ai_overview",
                "answer_box",
                "top_stories",
                "inline_videos",
                "shopping_results",
                "related_questions"
            ]
        }
    }


# 2. Save today's normalized results
today_file = f"serp_{date.today()}.json"

with open(today_file, "w", encoding="utf-8") as f:
    json.dump(today, f, indent=2, ensure_ascii=False)

yesterday_file = f"serp_{date.today() - timedelta(days=1)}.json"

if os.path.exists(yesterday_file):
    with open(yesterday_file, encoding="utf-8") as f:
        yesterday = json.load(f)

    for keyword in keywords:
        if keyword not in yesterday or keyword not in today:
            continue

        old = {
            item["link"]: item["position"]
            for item in yesterday[keyword]["organic_results"]
        }
        new = {
            item["link"]: item["position"]
            for item in today[keyword]["organic_results"]
        }

        print(f"\nKeyword: {keyword}")

        for link in new.keys() - old.keys():
            print(f"NEW: {link} at position {new[link]}")

        for link in old.keys() - new.keys():
            print(f"DROPPED: {link}, was at position {old[link]}")

        for link in old.keys() & new.keys():
            if old[link] != new[link]:
                print(f"MOVED: {link}, {old[link]} -> {new[link]}")

        old_features = yesterday[keyword]["serp_features"]
        new_features = today[keyword]["serp_features"]

        for feature in new_features:
            if old_features.get(feature) != new_features[feature]:
                print(
                    f"SERP FEATURE CHANGED: {feature}, "
                    f"{old_features.get(feature)} -> {new_features[feature]}"
                )
else:
    print("No yesterday snapshot found. Run the program again tomorrow to compare.")
Conclusion
We've built a simple workflow that retrieves Google Search results using SerpApi, stores daily snapshots, and compares those snapshots to identify organic ranking movements and SERP feature changes.
The same foundation can support more advanced functionality, such as competitor visibility analysis, weekly trend reports, alerts, and LLM-generated summaries.
The central idea is straightforward: collect the evidence, preserve the history, detect the changes, and then interpret them. That gives us a more useful starting point for SEO monitoring than looking at today's rankings in isolation.
Wrapping up, here are a few other blog posts that can help you with understanding SEO:
If you have any questions, we're happy to help via our web chat or email us at contact@serpapi.com.